
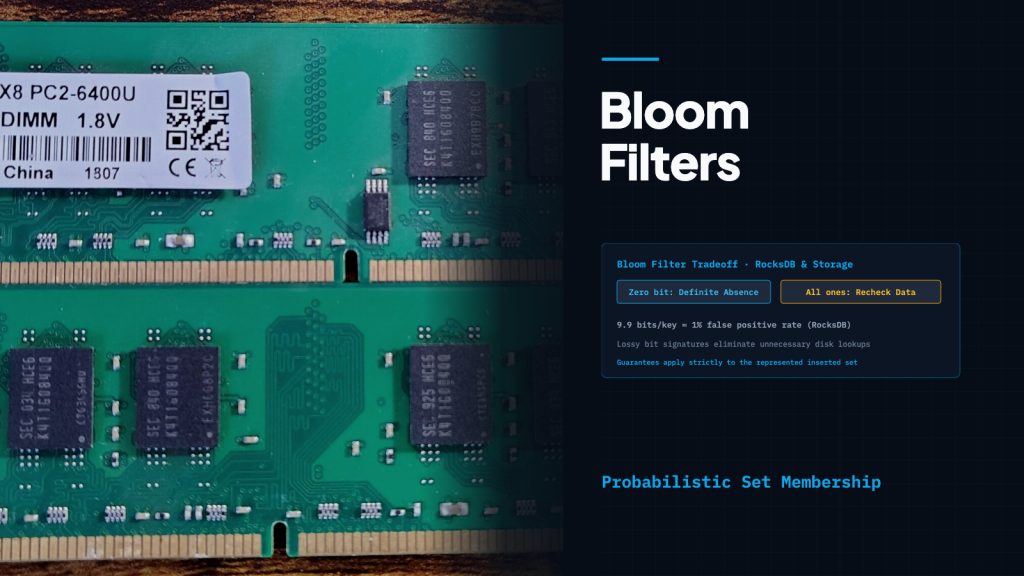
RocksDB’s Bloom-filter guidance puts a one-percent false-positive rate at approximately 9.9 bits per key. With that compact filter, the storage engine can skip a search whenever the answer is negative. A positive answer still means checking the stored data.
The filter saves space by allowing some false positives while preserving definite negative answers about the keys inserted into it. A compact filter rules out candidates, and the underlying data supplies the exact answer.
A small test before a larger search
RocksDB’s Bloom-filter documentation describes filters embedded in newly created sorted string table files, or SST files, when filtering is configured. Each filter represents a set of keys associated with stored data. Before searching that data, RocksDB can ask whether the target key could be present.
A negative answer eliminates the represented key set from consideration. A positive answer leaves it in consideration and requires further checking. The filter does not return the value associated with a key, and a positive result does not establish membership.
The scope matters. A filter associated with one file answers a question about that file’s represented keys. It does not independently establish whether a key exists anywhere in the database.
The design of these filters has also changed to reduce memory costs. RocksDB’s documentation records an older format that built separate Bloom filters for two-kilobyte regions of key/value storage, which still required loading the file index before checking the filter. Its later full-filter design created one filter for the entire SST file, limiting key probes to a single cache line in the central processing unit (CPU) to reduce memory misses while keeping the same negative-answer guarantee.
How shared bits produce one-sided error
The mechanism starts with an array of bits. Inserting a key applies hash functions that map it to positions in that array, then sets those positions to one. Checking a key examines positions calculated in the same way.
If any checked position contains zero, the key was not inserted: insertion would have set that position to one. If all checked positions contain one, however, the answer remains uncertain. Other keys can have set the same positions.
For an illustrative example, suppose a key maps to several positions already set by other insertions. Its check finds only ones even though that key was never added. This is a false positive. The filter has retained a compact pattern of shared bits rather than an exact list of keys.
Guava, Google’s Java utility library, states the insertion contract directly: after an element is put into its Bloom filter, subsequent membership checks for that element return true. Its checking method is named mightContain, making the uncertainty of a positive answer explicit.
Exact results come from checking the data
PostgreSQL 18’s bloom index extension applies the same broad principle through compact signatures of indexed attributes. These signatures can exclude nonmatching rows, but they are lossy representations: a candidate can pass the signature test without matching the actual query.
The PostgreSQL documentation therefore requires index results to be rechecked against the actual stored attribute values. A false positive creates extra checking work, but the recheck keeps it from becoming an incorrect query result.
This particular extension supports equality searches rather than range searches. Its documentation identifies tables with many attributes queried in varying combinations as a useful setting. Those are properties and use cases of PostgreSQL’s implementation, rather than promises about every Bloom filter.
What a one-percent false-positive rate means
The denominator is easy to misread. Guava defines false-positive probability as the probability of returning true for an element that was not inserted. RocksDB’s documentation likewise calculates its observed rate among queries for keys or prefixes absent from the represented file.
A one-percent rate therefore concerns queries for absent elements. It does not mean that one percent of all positive answers are wrong. The share of positive answers that are false also depends on how often the queried elements are genuinely present.
This distinction affects how a filter’s usefulness is assessed. A workload that frequently asks for absent keys gives the filter opportunities to rule out searches. The relevant saving is the work avoided, weighed against the filter’s own memory and processing costs.
Accuracy consumes resources
RocksDB’s configuration guidance gives approximately 9.9 bits per key for a one-percent false-positive rate and 15.5 bits per key for a 0.1-percent rate. These are implementation-specific sizing figures, not universal measurements for every Bloom-filter design.
Using more space can reduce unnecessary searches, but the filter itself also consumes processing time. PostgreSQL describes a related tradeoff: larger signatures reduce false positives and unnecessary visits to stored rows, while making the index larger and slower to scan.
Capacity planning matters as well. Guava warns that inserting substantially more elements than expected can saturate a fixed filter and sharply worsen its false-positive probability. More inserted keys set more of the available bits, making an all-ones answer less selective.
Redis offers a different implementation choice. Its BF.RESERVE command creates a filter that, by default, adds sub-filters when capacity is reached. Maintaining and querying those sub-filters uses additional memory and processing time. With NONSCALING selected, the command documentation says the filter returns an error when capacity is reached.
The represented set defines the guarantee
The insertion contract also sets a boundary for application design. If a separate filter is meant to represent database records, those records must actually be added using a consistent representation. A record omitted from the filter is outside what its negative answer can establish.
That is an engineering consequence of the contract: an incomplete or lagging filter cannot prove current absence from a database. The application must maintain the relationship between its filter and its authoritative data.
Within the represented set, the division remains precise. A zero bit rules out the candidate. An all-ones result sends the search onward to the actual data.
Related stories
Sources
- RocksDB Bloom Filter — mechanism, file scope and configuration tradeoffs
- Guava 33.4.8-jre BloomFilter API — membership contract, false-positive probability and saturation
- PostgreSQL 18 bloom index documentation — signatures, rechecks and limitations
- Redis BF.RESERVE reference — capacity, scaling and resource costs
- Featured image: SaltyCruton; Wikimedia Commons; CC0 1.0 (adapted from the original)
 SIGNAL TITANS

Leave a Reply