
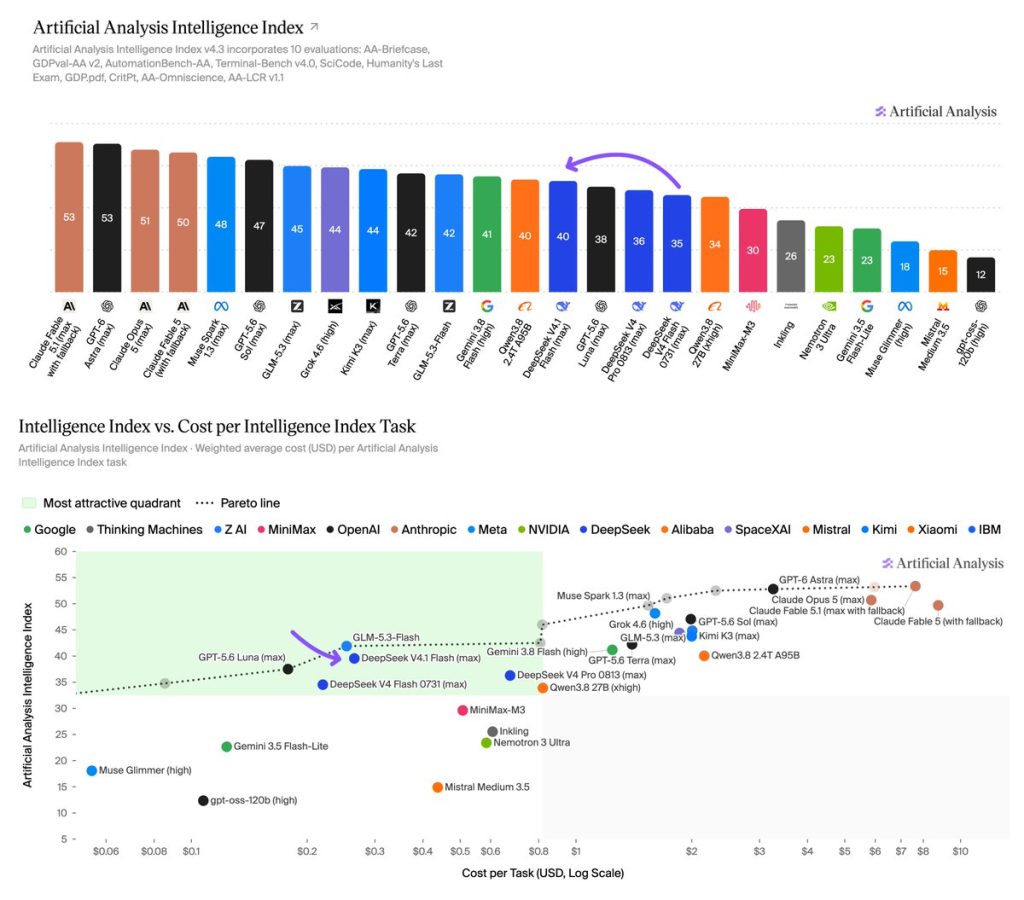
DeepSeek V4.1 Flash overtakes DeepSeek V4 Pro 0813 as DeepSeek’s new flagship model with a score of 40 on Artificial Analysis Intelligence Index. At just 552B parameters, it outperforms the Pro (1.6T) model while costing ~4x less per token, placing it just short of the Intelligence vs. Cost Pareto frontier because of its verbosity
deepseek_ai has released DeepSeek V4.1 Flash, the successor to DeepSeek V4 Flash 0731. This is a 552B model features a new causal Encoder–Decoder architecture, allowing it to have just 8B active parameters for input and 16B active parameters for output.
On the first-party API, DeepSeek V4.1 Flash is priced at $0.30 per 1M input tokens and $1.20 per 1M output tokens, with cached input tokens priced at just $0.006 per 1M tokens, a 98% discount. Off-peak pricing provides a further 50% discount across input, cached input, and output tokens. V4.1 Flash is ~20% cheaper than DeepSeek V4 Flash 0731 and ~4x cheaper than DeepSeek V4 Pro 0813 while delivering a higher performance.
Key results:
➤ DeepSeek V4.1 Flash makes gains in agentic capabilities and long context reasoning. DeepSeek V4.1 Flash scores 27% in Terminal-Bench v4.0, more than double DeepSeek V4.0 Flash’s 27%. Its GDPval-AA v2 rises 164 Elo points from 1468 to 1632, placing V4.1 Flash ahead of Kimi K3 (1584). DeepSeek V4.1 Flash also scores 84% on AA-LCR v1.1, at the same level as GPT-5.6 Sol (84%) and Gemini 3.8 Flash (84%). With a 1M token context window, this makes it a strong option for long-document and large-repository work at flash-tier pricing.
➤ DeepSeek V4.1 Flash takes first place on AutomationBench-AA with 69%, equal to GPT-6 Astra (69%) and slightly above Grok 4.6 (67%). AutomationBench-AA measures agentic workflows across 657 tasks spanning 39 SaaS applications including Salesforce, Jira, Gmail, Zendesk and Google Sheets, scoring whether a model completes the objective without tripping a guardrail. DeepSeek V4.1 Flash gains 15 percentage points over DeepSeek V4 Flash 0731 (54%), sitting 12 points above DeepSeek V4 Pro 0813 (57%) and 7 points above GLM-5.3 (62%).
➤ DeepSeek V4.1 Flash is one of the most verbose models we’ve measured at 89k Tokens per Intelligence Index Task. That is 25% more than Z AI's flagship GLM-5.3 (71k), 29% more than GLM-5.3-Flash (69k), and 62% more than DeepSeek V4 Pro 0813 (55k). It uses more output tokens than even the frontier models, including Fable 5.1 (78k) and Claude Opus 5 (73k).
➤ Despite such verbosity, DeepSeek V4.1 Flash still costs just $0.27 per Intelligence Index task. This is primarily driven by its low pricing at $0.30 per 1M input tokens and $1.20 per 1M output tokens, with cached input tokens priced at just $0.006 per 1M tokens, a 98% discount. That is ~7x below both GLM-5.3 ( $2.01) and Kimi K3 ($2.00), and ~2.5x below DeepSeek V4 Pro 0813 ($0.67).
Additional model details:
➤ Context window: 1M tokens
➤ Pricing: $0.30 / $1.20 per 1M input/output tokens on DeepSeek's first-party API, with a 98% cache hit discount ($0.006 per 1M cached input tokens)
➤ Input modalities: text and image
➤ Size: This is a 763B total parameters, 8B active parameters input and 16B active parameters output
➤ License: MIT
➤ Providers: DeepSeek first-party API
 SIGNAL TITANS
Leave a Reply