
AI-generated editorial illustration; not a documentary photograph.
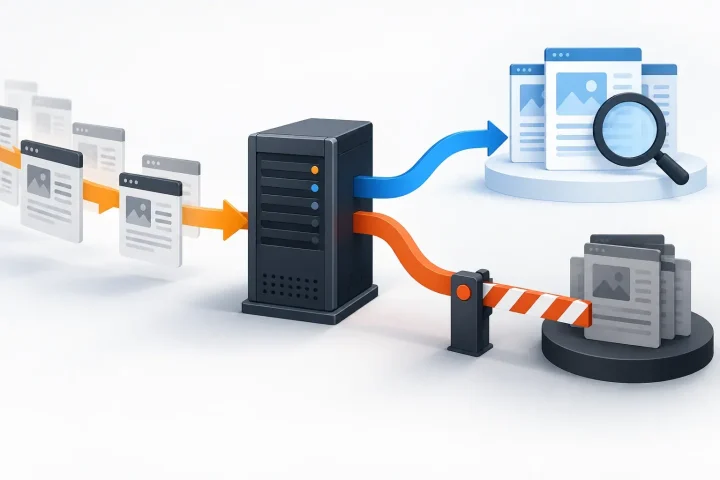
Cloudflare has introduced Disallow AI Training, a domain-level setting intended to let websites remain accessible to search indexing while refusing use of their content for AI model training. The control is available across all Cloudflare plans through Security Settings.
Mixed-Use Crawlers Get Separate Treatment
The setting addresses crawlers that serve both search and model-training purposes. Cloudflare says Applebot, Googlebot and Bingbot qualify for its new Accountable designation because their operators provide relevant controls or have made time-bound commitments to add them. Under Disallow AI Training, these crawlers can continue indexing a site for search rather than being blocked entirely.
Cloudflare publishes the applicable no-training preference through robots.txt using Bot Preference Sync. It also blocks other training crawlers, including training-only crawlers operated by Amazon, Anthropic, Meta and OpenAI, without affecting separate search crawlers from those companies.
Blocking Rules Now Carry More Risk
Cloudflare has changed its Block and Block on pages with ads options so they now cover mixed-use crawlers, including Applebot, Bingbot and Googlebot. Selecting either option can therefore affect both AI training and search visibility. Sites that want to preserve search access while expressing a training opt-out should use Disallow AI Training instead.
The company is also deprecating Block AI Bots in favor of separate Search, Training and Agent controls. Managed Robots.txt will be replaced by Bot Preference Sync, while existing configurations will be migrated to preserve their practical effect in most cases.
Bing Support Is Not Yet Automatic
The new setting does not currently transmit a robots.txt training opt-out to Bing. Microsoft is targeting early 2027 for domain-level support; until then, site owners can use Bing's NOARCHIVE tag or its URL blocking and content removal tools. Apple uses Applebot-Extended, while Google supports Google-Extended for training opt-outs.
Summary Controls Come Next
Cloudflare says it aims by early next year to offer controls over how much site content can appear in AI summaries, configured once through Cloudflare rather than separately with each operator. That work remains a stated goal, and the current release focuses on crawler access for training, search and user-directed agents.
Source: Have it both ways: stay discoverable in search while disallowing AI training
 SIGNAL TITANS
Leave a Reply