
In April 2005, Matt Mackall announced Mercurial version 0.1, a version control prototype written in fewer than 600 lines of Python. The tool already managed its own source code; Mackall wanted it to store and retrieve thousands of file revisions without bogging down on disk access, and his storage design did it by mixing compact deltas with occasional full snapshots.
In his announcement to the Linux kernel mailing list, Mackall noted that the repository format remained in flux and Mercurial could not yet handle file renames.
Early version control systems like the Source Code Control System (SCCS) and the Revision Control System (RCS) had established the tradition of saving differences rather than complete copies. Storing an entire duplicate of a large source file on every commit quickly exhausts disk capacity. Yet pure delta compression introduced a severe penalty of its own. In a naive delta chain, reconstructing revision 1,000 requires reading the original base revision and applying 999 individual patches in sequence. As history lengthened, retrieving older files became an expensive exercise in disk seeks and processor overhead.
The Revlog: Decoupling Index from Data
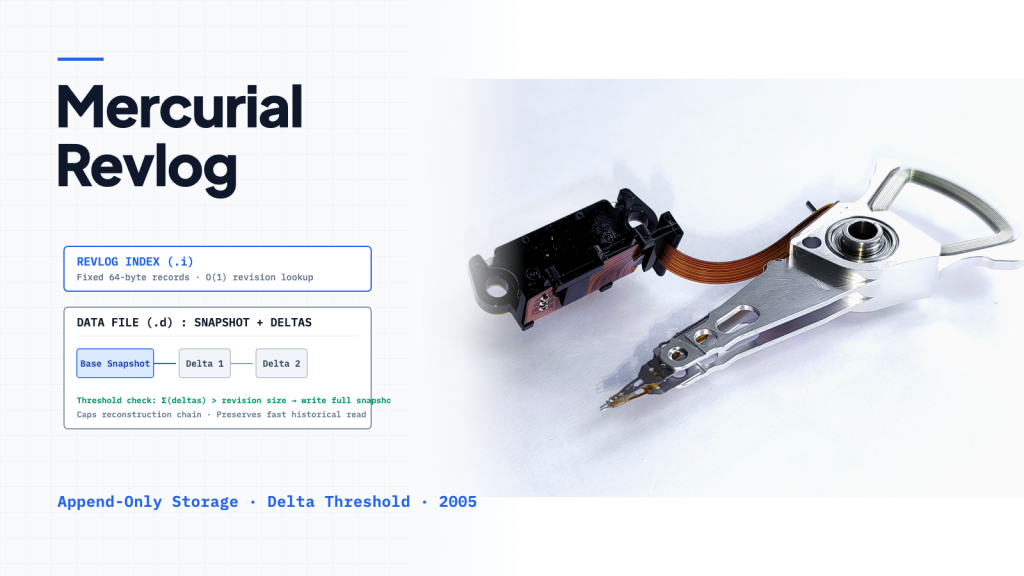
To break that bottleneck, Mackall designed the revlog, a unified storage structure that Mercurial applied across file histories, directory manifests, and commit metadata. A revlog separates metadata from raw file contents by maintaining two files on disk: an index file ending in .i and a data file ending in .d. For small files without much history, Mercurial combines both into a single index file to avoid unnecessary disk operations.
The index consists of fixed-length 64-byte records containing file offsets, compressed lengths, uncompressed sizes, base revision pointers, parent identifiers, and cryptographic hashes. Because every record in the index occupies the exact same number of bytes, locating any revision requires only multiplying the record size by the revision number. This fixed structure delivers constant-time access to revision metadata, allowing Mercurial to find where a file revision lives on disk without scanning through megabytes of source text.
Knowing When to Spend Disk Space
The critical engineering decision inside the revlog was how to decide when to store a delta and when to store a full copy. Instead of scheduling snapshots at arbitrary intervals like every hundred commits, Mercurial measures the cumulative byte size of deltas stored since the last base snapshot. When the total volume of accumulated deltas exceeds a threshold relative to the uncompressed length of the revision, Mercurial stops appending deltas and writes a fresh, compressed full snapshot of the file.
This threshold rule limits accumulated delta data relative to revision size. Reconstructing a revision requires its base snapshot and the intervening deltas; the byte-based threshold does not impose a fixed maximum number of deltas. Furthermore, Mercurial checks whether compression actually reduces the stored size. If a file is already compressed, such as an image or an archive, recompressing it can produce a larger output. When compression yields no space savings, Mercurial stores the snapshot or delta uncompressed.
Write Ordering and Lockless Concurrency
Mercurial layers its entire repository model on top of this revlog primitive. Individual file revisions are stored in filelogs. Above them, directory manifests track which file revisions belong to each commit. At the top level, the changelog records commit messages, timestamps, and pointers to the corresponding manifest revisions. Writes always proceed from the bottom up: Mercurial appends new revisions to filelogs first, writes the manifest second, and updates the changelog last.
Because every upper layer points down to already-written data, any process reading the changelog is guaranteed that its references are valid and complete. Readers never observe partially written commits and do not need to take repository read locks, even while a commit transaction is actively writing new data. A simple process lock protects against concurrent writers, leaving read operations fast and non-blocking.
The Cost of File-Centric History
Optimizing revision storage around individual files carried an architectural tradeoff. In his 2011 architectural review, Dirkjan Ochtman attributed inefficient renames to the separate storage of revisions for each file. Filelogs could already record copies and renames through optional metadata prefixes, but he anticipated that making renames efficient would require crossing an architectural layer boundary.
Building a version control system means choosing which resource to spend. By spending storage on periodic snapshots, Mercurial ensured that reconstructing a past version of a file remained bounded by data size rather than the depth of its commit history.
Related stories
Sources
- Linux Kernel Mailing List: Mercurial v0.1 – a minimal scalable distributed SCM (Matt Mackall, April 2005)
- The Architecture of Open Source Applications, Volume 1: Mercurial (Dirkjan Ochtman, 2011)
- Mercurial: The Definitive Guide: Behind the scenes (Bryan O’Sullivan)
- Mercurial: The Definitive Guide: How did we get here? (Bryan O’Sullivan)
- Linux Kernel Mailing List: Mercurial 0.4b vs git patchbomb benchmark discussion (Matt Mackall, April 2005)
- Featured image: Mk2010; Wikimedia Commons; CC BY 4.0 (adapted from the original)
 SIGNAL TITANS

Leave a Reply